
A system learns to spot wolves in photos, then fails when the snow disappears. It may have learned a shortcut instead of the animal. Deep learning explained becomes much clearer when success on familiar examples is treated as the start of a test, rather than the end of one.
Training means changing a set of internal values
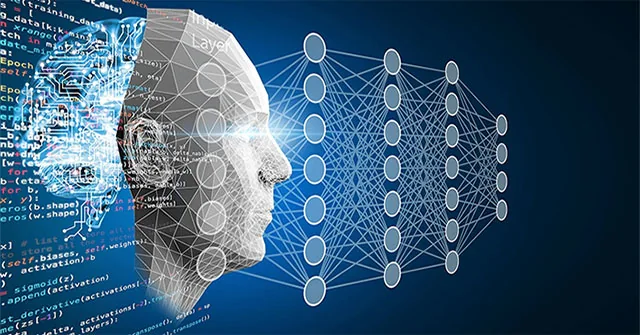
Neural networks process examples through linked layers of calculations. During training, a learning method adjusts internal values to reduce an error score. The system does not need a person to write a separate rule for every image, but people still choose its task, data, and ways of measuring success.
For a picture task, early steps may respond to simple visual patterns. Later steps can combine those signals in more complex ways. These layers are useful mathematical tools.
Their names do not show that the system thinks or experiences the world as a person does.
Good examples are only part of the challenge
Training data shapes which patterns a model can learn. If the examples contain labels, the system tries to connect inputs with those labels. Missing groups, wrong labels, repeated images, or clues unrelated to the real task can all make apparently strong results less useful outside the training set.
A collection of cats photographed indoors and dogs outdoors offers an easy trap. The model might use the background. It can score well without learning the feature a person intended, which is why building a good dataset needs care as well as size.
Related Stories
Memorizing a lesson is not passing a new test
Overfitting happens when a model fits its training examples too closely and performs poorly on new ones. The pattern may include chance noise or narrow quirks. Test data kept apart from training gives a better check of whether the learned rule works beyond the examples already seen.
This is like studying an answer sheet rather than the subject. The comparison is limited. But the test is useful.
If near-copies leak into both sets, the result may exaggerate progress. A clean split makes that hidden advantage harder to mistake for skill.
A high score needs a clear description
Pattern recognition can be measured in several ways, and one score rarely tells the whole story. Missing a dangerous case may matter more than raising a false alarm. A useful report states what was tested, which kinds of mistakes occurred, and how closely the test matches the intended use.
A model built for crisp studio photos may face dim, blurred images in the field. Its old score does not automatically carry over. Checking performance under those conditions is part of the work, rather than a minor detail after the model has been announced.
More data is helpful when it adds useful variety
A larger dataset can improve a model, but repeated or poor examples do not guarantee a better result. Useful variety, sound labels, appropriate methods, and testing all matter. The goal is a system that handles the task well when conditions change in the ways its users actually face.
This is why an impressive demo should invite specific questions. What happens with a rare case? What happens when the camera changes?
A trustworthy account can show both the useful result and the point where the system stops being dependable.
Frequently Asked Questions
A model can score well and still use the wrong clue. These questions show why a fresh test matters. They also place deep learning within the wider AI field, rather than treating one useful method as a complete model of thought or proof that a machine knows what it sees.
Is deep learning the same as all artificial intelligence?
No, it is one group of methods in a much wider field. Other systems can use rules, search, or other forms of learning to solve tasks that need a different approach.
Why keep test data separate?
It tests examples the model did not train on. If the same picture, or a close copy, turns up in both sets, a strong score may hide a weak ability to handle new cases.
Does a larger model always perform better?
No, Size is only one factor in a result. Poor data or a bad task match can still teach the wrong rule, even when a model has many more internal values to adjust.